Traditional test reports
The question you tested
Once your traditional test has been running, its report brings together the traffic, conversions, and statistical evidence you need to understand how each variation is performing.
A traditional test is built around comparison. The base and each variation are measured against the same goal so you can answer two questions:
- Which experience is performing better?
- Is there enough evidence to trust that difference?
For this lesson, we’ll use a simple CTA copy test to practice reading the report.
The test compares the original “Learn more” CTA with a new “Sign up today” variation.
Before we answer it, let’s get familiar with what you can find in the report.
What's in the report?
A traditional test report brings together the test result and the supporting context you can use to understand it.
You’ll typically see these key areas:
Highlights
A summary of the test’s current state.
Variations
Performance for the base and each variation.
Audience insights
Additional context about how visitor groups responded.
Account engagement
Additional context about how known accounts engaged with the optimization (when available).
Performance over time
How conversion rates changed during the test.
Traffic allocation over time
How traffic was distributed between the base and variations.
Here’s a full traditional test report so you can see how the main sections fit together before we look at them more closely.

You don’t need to interpret everything at once. For a traditional test, use this sequence:
- See which variation is ahead
- Check whether there’s enough evidence to trust the difference
- Use the rest of the report for context
- Decide what to do next
See which variation is ahead
Start with the Variations table. It gives you the clearest view of how each experience is performing against the selected goal.
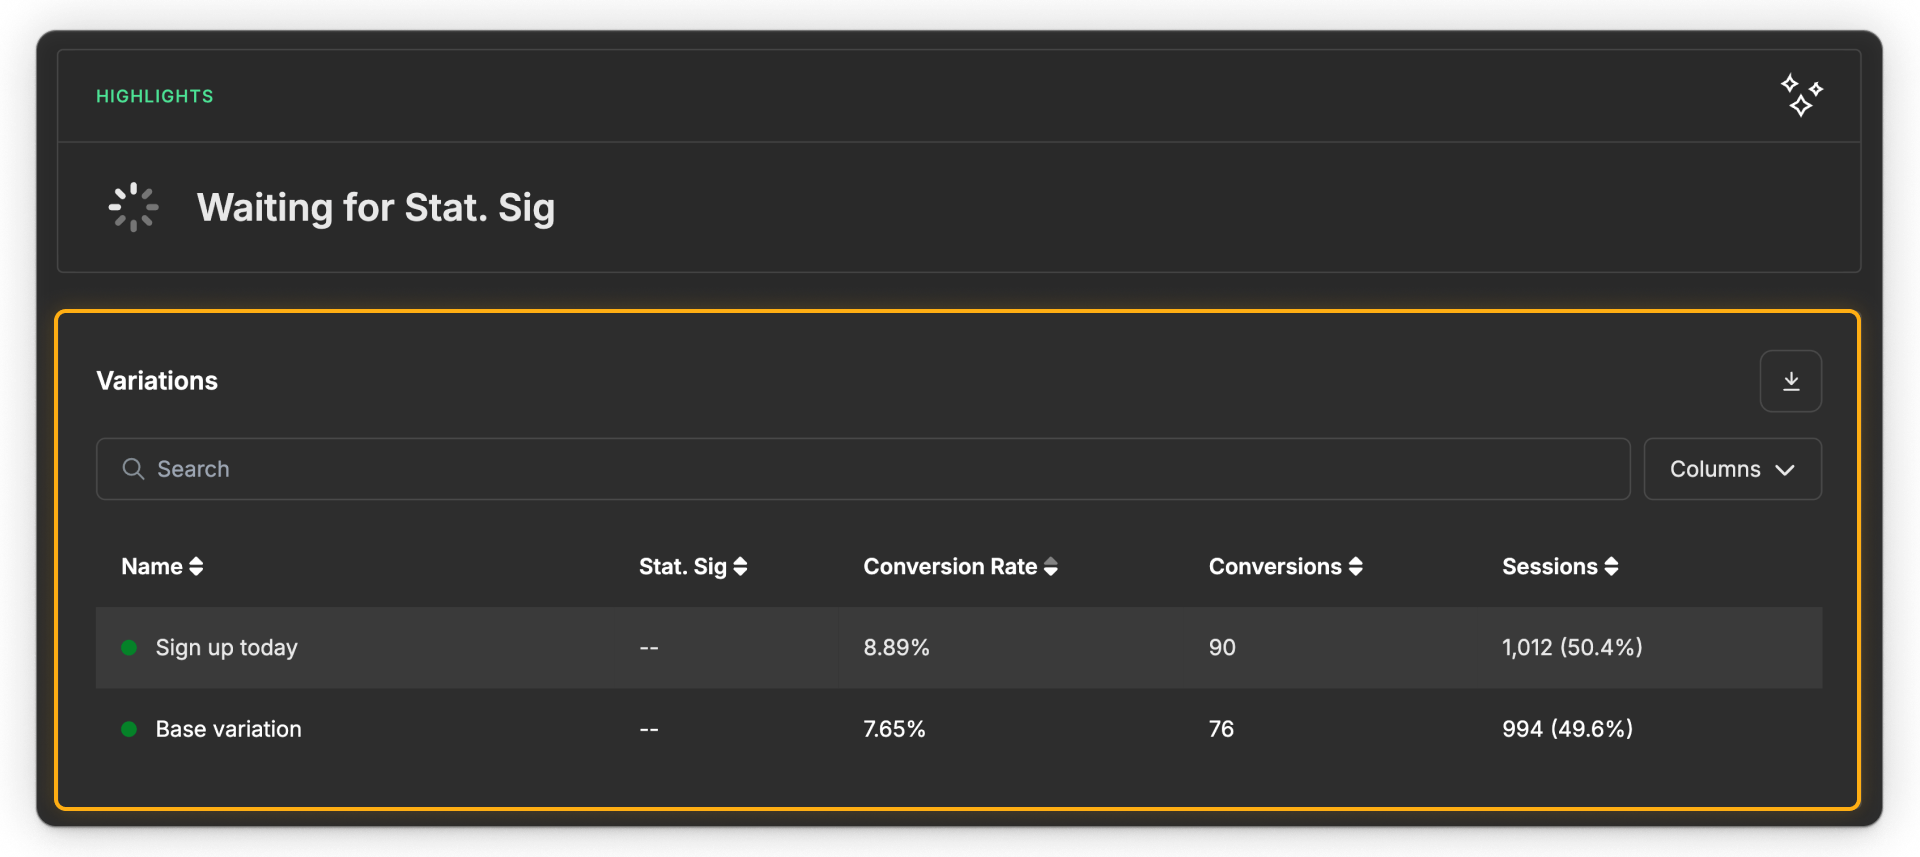
For each variation, you can see:
Sessions
How many browsing sessions were attributed to each variation.
Conversions
How many times visitors completed the action tracked by the selected goal.
Conversion rate
The number of conversions divided by sessions for that variation.
Statistical significance
How much evidence there is that a variation’s performance compared with the base reflects a real difference rather than normal fluctuation.
In our CTA test example, "Sign up today" is ahead so far.
"Learn more"
- 994 sessions
- 76 conversions
- 7.65% conversion rate
"Sign up today"
- 1,012 sessions
- 90 conversions
- 8.89% conversion rate
But notice the Highlights section still says "Waiting for Stat. Sig".
A higher conversion rate tells you which variation is ahead so far. It doesn’t tell you whether that lead is strong enough to trust.
That’s where statistical significance comes in.
Check whether the difference is trustworthy
In a traditional test, Optimize compares each variation with the base and estimates how reliable the observed difference appears to be.
Higher statistical significance means there’s stronger evidence that the performance difference reflects a real effect rather than normal fluctuation.
That evidence depends on more than conversion rate alone:
Time
Visitor behavior varies, so a test needs time to account for short-term spikes or unusual periods.
Sample size
More traffic and conversions give Optimize more evidence to compare.
Effect size
A large, sustained difference between a variation and the base may become clear sooner than a very small difference.
So even though "Sign up today" is currently converting at a higher rate, there may not yet be enough evidence to confidently call it the winner.
Tip: Don’t call the test too early
A variation can pull ahead early and fall back later. Give the test enough traffic, conversions, and time to build meaningful evidence before drawing conclusions.
When there's enough evidence
When the test reaches high statistical significance, Optimize can identify a winning variation. Until then, treat an early lead as just that — an early lead.

Explore the rest of the report
Once you understand which variation is ahead and how strong the evidence is, use the rest of the report to understand the result in more detail.
Audience insights
Audience insights show how the variations performed across available visitor signals.

For example, you might see performance broken down by traffic source, device, or other visitor attributes.
These patterns can help you generate new hypotheses. Maybe "Sign up today" performed particularly well for visitors arriving from paid search, for example.
Treat these insights as additional context rather than a replacement for the overall test result.
Account engagement
If account-level information is available, the report can also show how known accounts engaged with the optimization.

Use this when account behavior matters to your business or when company-level activity adds useful context to the result.
Performance over time
The performance chart shows how conversion rates changed throughout the test.
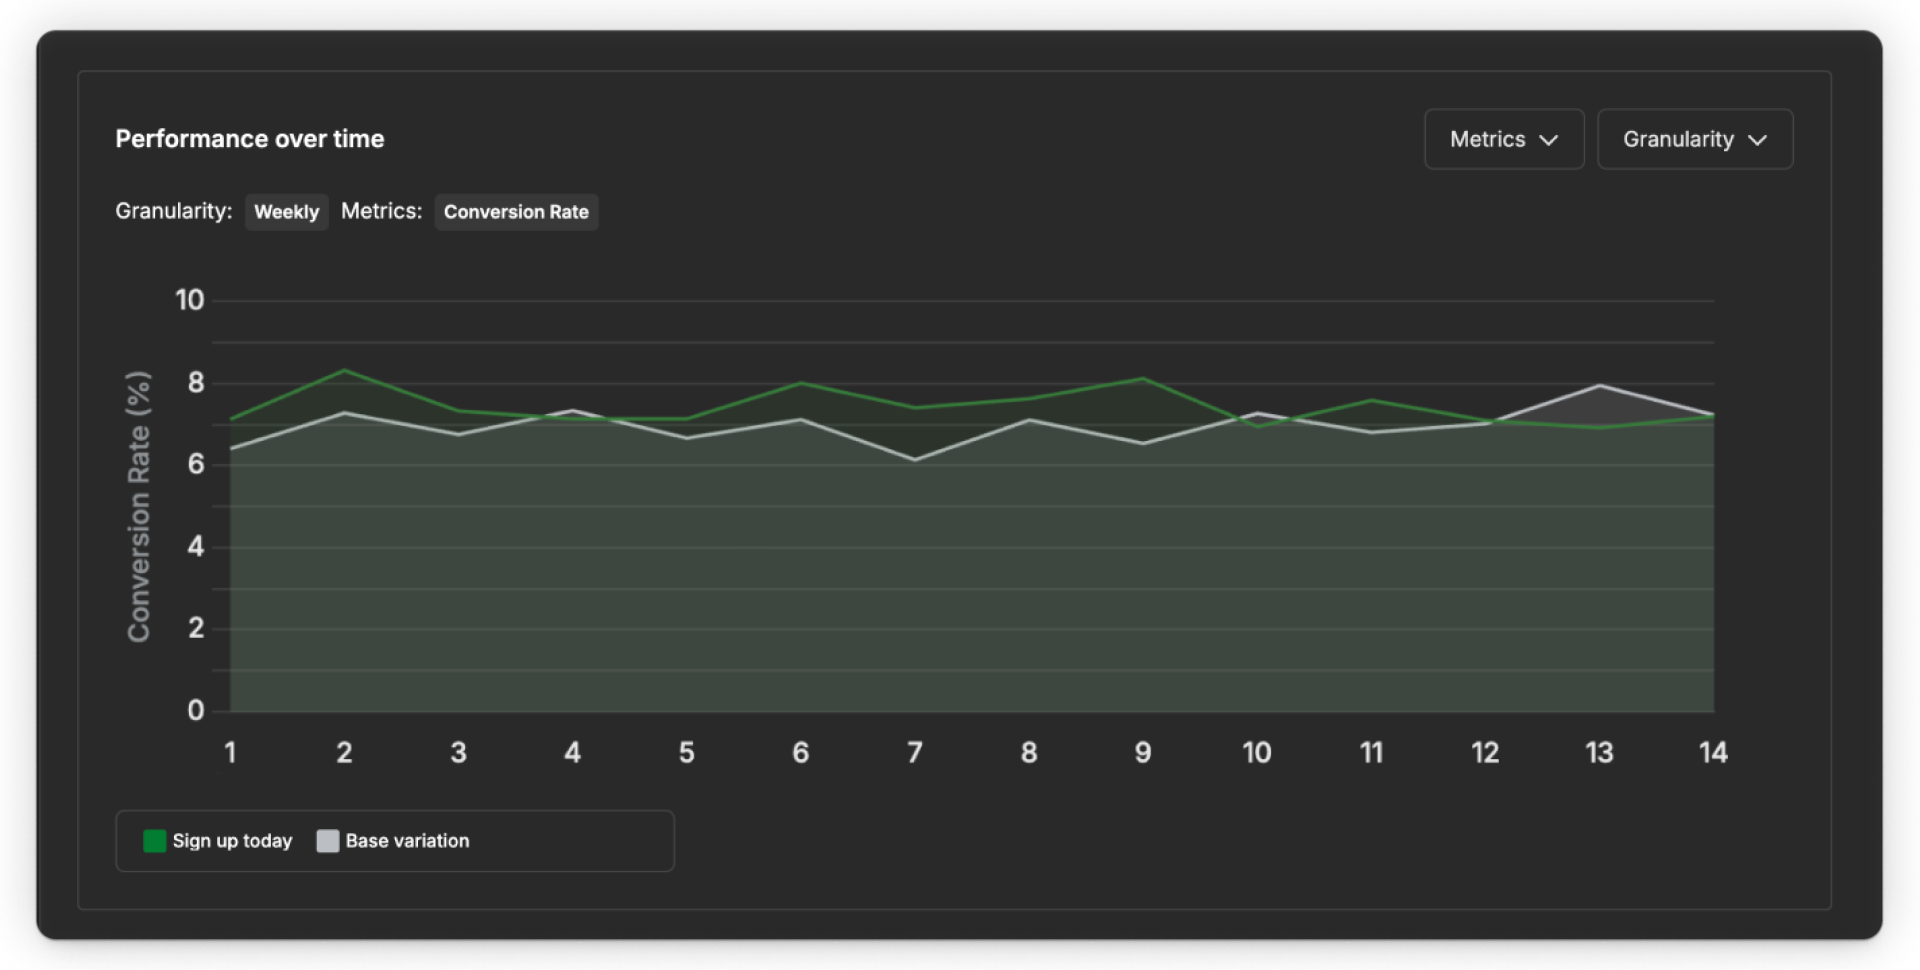
Use it to understand the shape of the result:
- Did "Sign up today" stay ahead consistently?
- Did performance change during the test?
- Did the difference emerge gradually or suddenly?
The headline result tells you where the test landed. The chart helps you see how it got there.
Traffic allocation over time
The traffic allocation chart shows how test traffic was split between the base and variation over time.

In this example, traffic stays close to a 50/50 split throughout the test.
The stacked chart shows the percentage of sessions assigned to each experience, while the bars below show the total number of sessions recorded during each time period.
For a traditional test, this allocation follows the traffic split you configured so each experience can collect enough data for comparison.
Decide what to do next
Once you know what’s ahead, how strong the evidence is, and what context surrounds the result, decide what the evidence supports.
You might:
Apply the winner
When the evidence is strong and the result supports your hypothesis.
Keep the test running
When the evidence is still inconclusive.
Iterate
When the result reveals a useful signal or raises another question.
Stop the test
When the change clearly isn’t helping.
Not every useful test has a winner. A flat or losing result can still tell you whether the change affected behavior, whether the difference mattered, and what question to explore next.
Each result should help inform what you optimize next.
Ready to keep going?
Continue to the next lesson where you’ll learn how to interpret manual personalization results, where the report looks familiar but the variations aren’t competing to find one overall winner.